Background
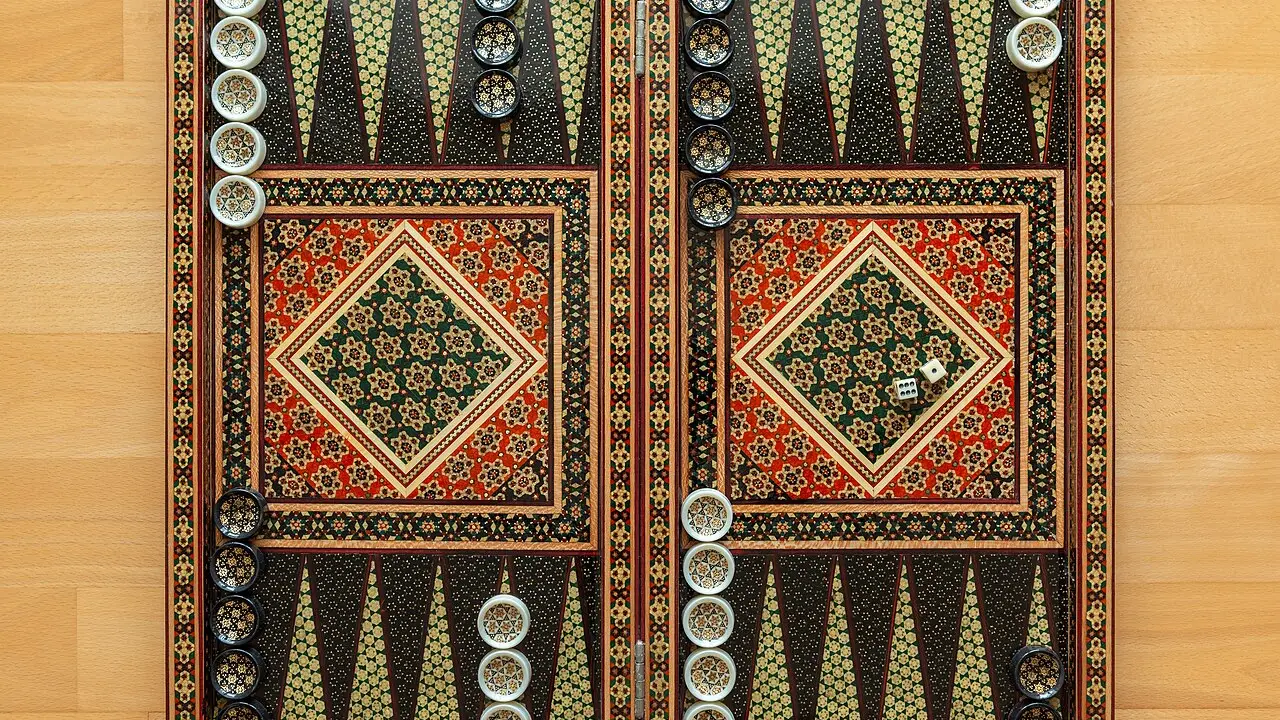
Backgammon is a board game in which dice decide which moves are available, so a program has to weigh immediate tactics against the long-term structure of a position, and a single roll can decide a game. TD-Gammon was developed in the 1990s by Gerald Tesauro at IBM's Thomas J. Watson Research Center [1]. Its name comes from the fact that it is an artificial neural network trained by a form of temporal-difference learning, specifically TD-Lambda [1].
How it worked
The core of TD-Gammon is a three-layer neural network: 198 input neurons code the board position, and four output neurons estimate the probability of each possible game result [1]. Rather than being supplied with knowledge about what a good position looks like, the network trains itself to be an evaluation function for backgammon by playing against itself and learning from the outcome [3][4].
Tesauro describes the general setting of such learning: an agent observes an input state, produces an output, and then receives a scalar reward. When the reward is delayed, the agent faces the temporal credit assignment problem — working out which of many earlier decisions deserves credit or blame [3][4]. The article cites two developments that made the approach promising: nonlinear function approximation schemes such as decision trees, spline fitting and multilayer perceptrons, and Sutton's temporal-difference methods [3][4].
In temporal-difference learning the network's estimate of the value of one position is updated toward its own later estimate, so the network learns from the difference between successive predictions instead of waiting for a label on every move.
Versions and results
In 1992 the program reached version 2.0, with 80 hidden units, 0.8 million training games and a 2-ply search [1]. Version 2.1, dated 1993, was trained with 1.5 million games of self-play and achieved a level of play just slightly below that of the top human backgammon players of the time [1]. In 1998, during a 100-game series, it was defeated by the world champion by a margin of only 8 points [1].
Why it mattered
TD-Gammon greatly surpassed all previous computer programs at backgammon. Tesauro writes, however, that it was developed to explore new ideas and approaches to reinforcement learning rather than to win games [3][4]. The program was designed to test multilayer neural networks trained by TD(lambda), and to compare TD learning with supervised training on a corpus of expert-labelled exemplars [3][4]. Along the way it explored strategies that humans had not pursued, and led to advances in the theory of correct backgammon play [1].
The work was published as "Temporal difference learning and TD-Gammon" in Communications of the ACM, Volume 38, Issue 3, pages 58–68, on 1 March 1995, with the author at IBM's Thomas J. Watson Research Center in Yorktown Heights, New York [2]; the March 1995 issue of the journal reproduces the article starting on page 58 of Volume 38, Number 3 [4].
TD-Gammon is commonly cited as an early success of reinforcement learning and neural networks, and was cited in papers on deep Q-learning and AlphaGo [1]. For later work in the field it served as a reference point: a system that had been given almost no backgammon knowledge, learned from self-play, and still ended up playing at a level close to the best humans of its time [1].
Sources
- 1TD-GammonWikipedia
- 2Temporal difference learning and TD-GammonCommunications of the ACM / ACM Digital Library
- 3Temporal Difference Learning and TD-Gammon (CACM 1995 article, reproduced with ACM permission)ACM / University of Western Ontario
- 4Communications of the ACM, March 1995, Vol. 38 No. 3, p.58Internet Archive / ACM
Cite this page: TD-Gammon developed at IBM. TellWorld, https://www.tellworld.net/news/td-gammon-1992. Updated 2026-11-07