Background
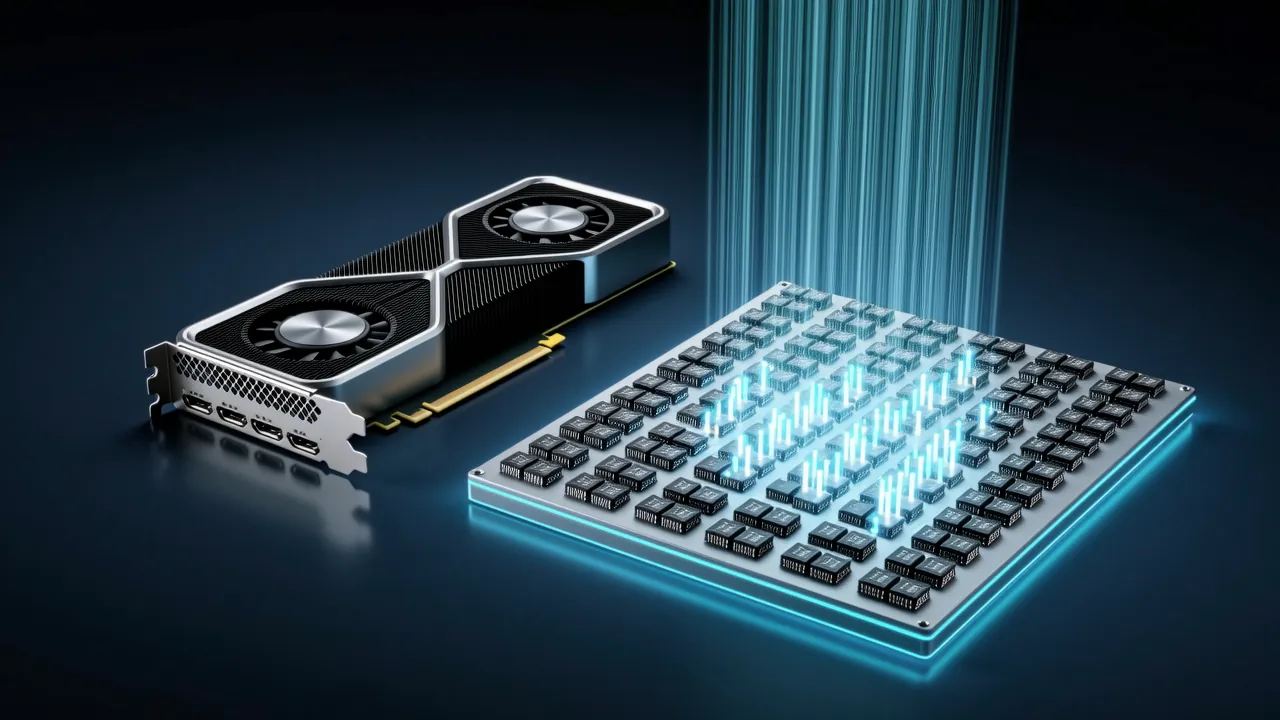
Graphics processors are built to do the same small operation on enormous numbers of pixels at once. For a long time that arithmetic capacity was reachable mainly through graphics interfaces, so a programmer who wanted to use a GPU for anything else had to disguise the work as drawing. CUDA changed that arrangement by exposing the chip's parallel cores to ordinary programs.
The announcement
On 8 November 2006, NVIDIA unveiled CUDA as a new computing architecture that let programmers use the GPU's hundreds of on-chip processor cores for general computation rather than graphics alone [2]. The company paired it with a C-compiler development environment for the GPU, which it described as an industry first [2]. At the unveiling the software development kit was made available to registered developers and researchers, and NVIDIA claimed speed-ups of as much as 100 times over traditional approaches for problems that suited the hardware [2]. The first hardware to run it was the GeForce 8800 graphics card [2].
What shipped in 2007
NVIDIA's toolkit archive dates CUDA Toolkit 1.0 to June 2007, with version 1.1 following in December 2007 [1]. The versioned toolkit was the practical form of the earlier announcement: a downloadable compiler and library set with which researchers could write GPU code without routing everything through the graphics pipeline.
How the model works
In the CUDA model, thousands of lightweight programs called threads run in parallel and can cooperate on a single problem [2]. The division of labour is deliberate: the GPU takes fine-grained, data-intensive work, while the CPU handles control and data management [2]. A task suits this arrangement when it can be cut into many pieces that are handled in much the same way — applying the same filter to every pixel of a large image, for instance — because then the pieces can be handed out to many threads at once. Work that must proceed step by step, with each step depending on the last, stays with the CPU.
Why it mattered
NVIDIA's corporate timeline describes CUDA as the step that opened the GPU's parallel processing capabilities to science and research [3]. The significance is structural: a chip designed for rendering became a general parallel processor that a researcher could program in a familiar language, and the same toolkit shipped to anyone who registered rather than being kept inside graphics work.
From graphics to deep learning
CUDA later became the base layer for GPU deep learning [1]. AlexNet, the 2012 network, was trained with a hand-optimised GPU convolution implementation running on GTX 580 cards [1]. In 2014 NVIDIA released cuDNN, a CUDA library of optimised deep-learning routines that sped up the Caffe framework by 36% on a standard model [1]. Today NVIDIA describes CUDA as its platform for accelerated computing — the software layer that lets applications use GPUs from languages such as C++, Python and Fortran, or through libraries and frameworks such as PyTorch [4].
Sources
- 1CUDA Toolkit ArchiveNVIDIA Developer
- 2NVIDIA Unveils CUDADigital Engineering 24/7
- 3
- 4CUDANVIDIA Developer
Cite this page: NVIDIA releases CUDA 1.0. TellWorld, https://www.tellworld.net/news/cuda-2007. Updated 2026-11-08